Ultimate AI Media Generation Platform
With 882+ top-tier models, A2E is the most powerful platform for AI image and video generation — built to help you create faster and scale without limits.
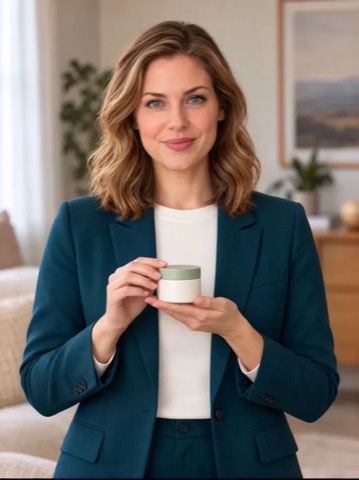
Animate a portrait image from an audio recording with Seedance 2.5. Generate talking-avatar videos in 480p or 720p, processing up to the first 120 seconds of audio.
Seedance 2.5 (Image-to-Video) generates Hollywood-grade cinematic videos from reference images and text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it preserves the input image's subject and composition while adding expressive, physically accurate motion.
Transfer the motion of a reference video onto a character with Seedance 2.5. Your character, from a picture or a short description, performs the same movements, gestures and camera motion as the video, in 480p, 720p or 1080p for up to 30 seconds. Ready-to-use REST inference API, best performance, no coldstarts, affordable pricing.
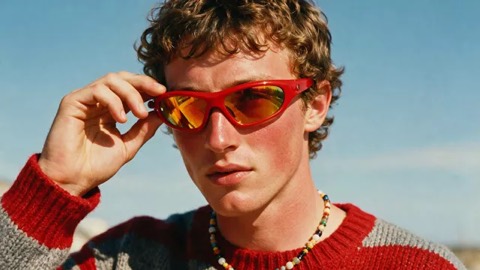
Seedance 2.5 (Video-Edit) edits an input video from a natural-language prompt. The reference video drives subject identity, composition, and motion while the model rewrites lighting, style, weather, environment, or specific elements as instructed. Built on ByteDance Seed's unified multimodal architecture for cinematic, motion-stable output.
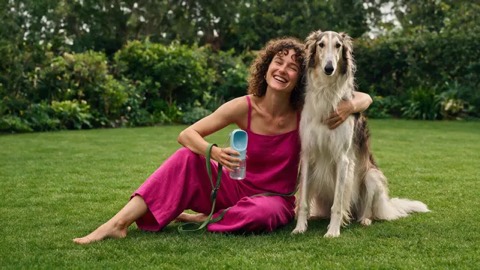
Seedance 2.5 (Video-Edit Turbo) is the turbo tier for editing an input video from a natural-language prompt — faster, more affordable high-resolution output while preserving subject identity, composition, and motion.
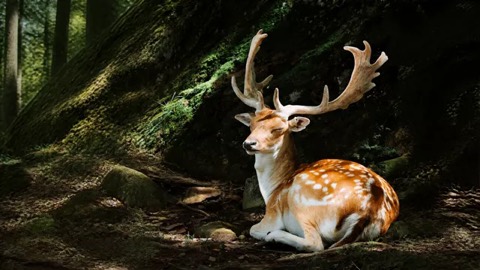
Seedance 2.5 (Video-Extend) extends an input video with a new cinematic continuation generated from its last frame and a natural-language prompt.
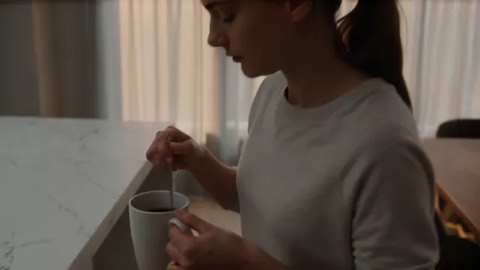
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
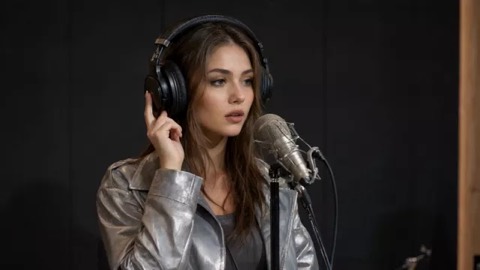
Seedance 2.5 (Text-to-Video) generates Hollywood-grade cinematic videos from text prompts with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture, it leads on instruction adherence, motion quality, and visual aesthetics. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
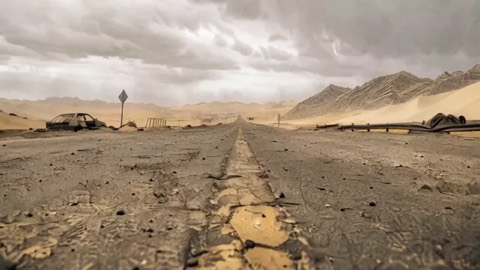
Seedance 2.5 (Image-to-Video Turbo) generates cinematic 720p/1080p videos from reference images and text prompts —a faster, more affordable high-resolution tier with native audio-visual synchronization, director-level control, and exceptional motion stability. Built on ByteDance Seed's unified multimodal architecture.
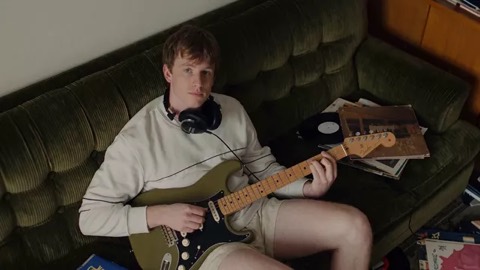
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.
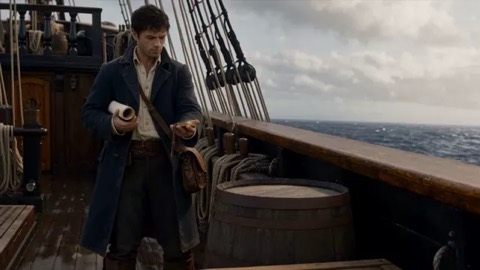
Seedance 2.5 (Text-to-Video Turbo) generates cinematic videos from text prompts at 720p and 1080p with native audio-visual synchronization, director-level camera and lighting control, and exceptional motion stability — optimized for turbo output. Built on ByteDance Seed's unified multimodal architecture. Ready-to-use REST inference API, best performance, no cold starts, affordable pricing.